A systematic review can look organized and still be difficult to defend.
The search results are neatly stored. The screening platform shows progress. The extraction table has rows and columns. The PRISMA diagram is polished.
But can the team explain why each source entered or left the review? Can another researcher reproduce the search? Do the numbers in the flow diagram match the screening record? Does every extracted value trace back to the correct report?
That evidence trail is the real systematic review workflow.
PRISMA 2020 gives researchers a 27-item reporting checklist, an expanded checklist, an abstract checklist, and revised flow diagrams for original and updated reviews. It also asks authors to report full search strategies, reviewer independence, and the use of automation tools (Page et al., 2021). But PRISMA is a reporting guideline, not a substitute for a protocol or a method.
The safest approach is to build the review so the final report is already supported by the decisions made along the way.
This guide walks through the systematic review process from protocol to PRISMA.
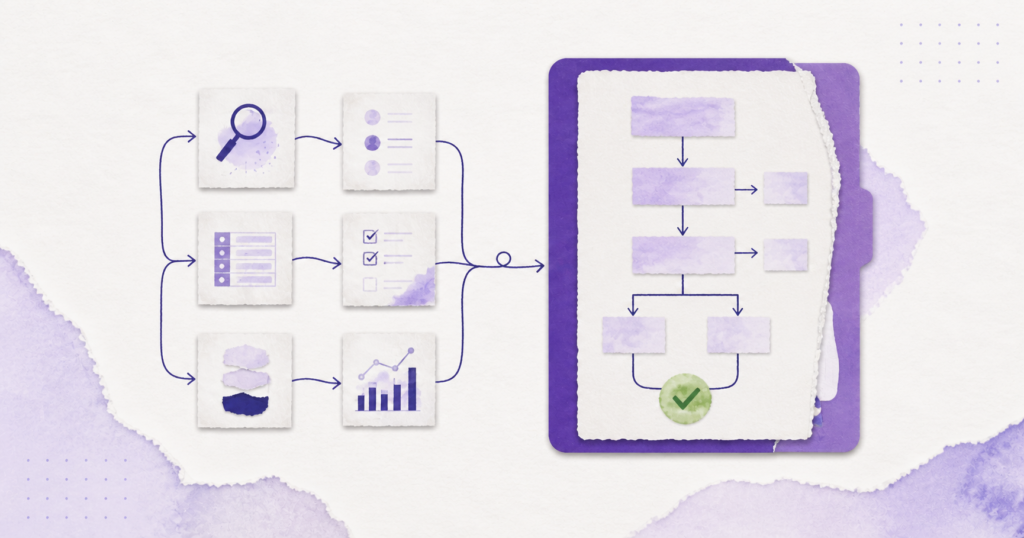
The systematic review workflow at a glance
| 1. Protocol | What question will the review answer? | Registered protocol and amendment log |
| 2. Search design | Where and how will you search? | Complete strategies, platforms, dates, and limits |
| 3. Retrieval and deduplication | Which records are unique? | Raw exports, duplicate log, and source totals |
| 4. Screening pilot | Do reviewers interpret the criteria consistently? | Pilot decisions and clarified rules |
| 5. Formal screening | Which reports meet the eligibility criteria? | Independent votes, conflicts, and exclusion reasons |
| 6. Data extraction | What information must be collected from each study? | Tested extraction form and source-linked entries |
| 7. Risk of bias | How might each result be distorted? | Design-appropriate domain judgments |
| 8. Synthesis | Which studies can be combined, and how? | Analysis plan, code, tables, and sensitivity checks |
| 9. PRISMA reporting | Does the published account match the review record? | Reconciled counts, checklist, and flow diagram |
| 10. Archiving and updates | Can the review be checked or updated later? | Search files, exports, decisions, code, and versions |
Each stage creates the inputs for the next. A weak handoff does not disappear. It becomes a downstream problem.
Step 1: Write the protocol before choosing the software
Start by fixing the decisions that should not change in response to the results.
Your protocol should define:
- The review question
- The population, intervention or exposure, comparator, and outcomes where relevant
- Eligible study designs
- Publication, language, date, and geographic criteria
- Information sources and planned search approach
- Title-and-abstract and full-text screening procedures
- Data items and extraction procedures
- Risk-of-bias tools
- Planned synthesis methods
- Reviewer roles
- The approach to disagreements
- Any planned automation
- The process for recording amendments
PRISMA-P provides a 17-item checklist containing 26 items when sub-items are counted. It organizes protocol reporting into administrative information, the introduction, and the methods (Shamseer et al., 2015).
The protocol does not need to predict every complication. It needs to make the original plan visible.
If the team later changes an outcome, eligibility rule, search source, or synthesis method, record:
- What changed
- When it changed
- Why it changed
- Whether the change was informed by the emerging results
- How the change could affect the conclusions
Do not silently replace the original plan with a cleaner version. A dated amendment log is more credible than a protocol that appears to have anticipated every problem.
Practical checkpoint: Could a new team member read the protocol and make the same decisions without relying on unwritten context?
Step 2: Build a reproducible search
A database search is not reproducible because it contains many keywords. It is reproducible when another researcher can see exactly what was searched, where it was searched, and when it was run.
For every database, register, website, or other source, preserve:
- The database name
- The platform or interface
- The full search strategy as executed
- The search date
- Date or language limits
- Filters
- The number of results retrieved
- The export format
- The raw exported file
PRISMA-S adds a 16-item checklist specifically for reporting search methods and information sources (Rethlefsen et al., 2021). PRISMA 2020 also calls for the full search strategies used for all databases, registers, and websites searched, rather than one representative query (Page et al., 2021).
Peer-review the search before running it everywhere
One missing parenthesis or poorly chosen limit can remove eligible studies before screening begins.
The PRESS guideline gives search reviewers six areas to inspect:
- Translation of the research question
- Boolean and proximity operators
- Subject headings
- Text words
- Spelling, syntax, and line numbers
- Limits and filters (McGowan et al., 2016)
Review the primary strategy before translating it into every database. Fixing a mistake once is easier than repairing several searches and recalculating the full workflow later.
A librarian or information specialist can also spot a broader problem: a search that is technically valid but poorly matched to the language of the field.
For help selecting appropriate discovery sources, see our guide to the best sites like Google Scholar.
Practical checkpoint: Could another researcher rerun every search without asking what a line, filter, or database name meant?
Step 3: Preserve the raw exports before deduplication
Save each database export before importing, combining, or cleaning anything.
Those untouched files preserve:
- The original result count from each source
- The metadata each database supplied
- The starting point for deduplication
- Evidence needed to investigate missing or merged records
- The figures required for the PRISMA identification stage
Use clear filenames such as:
medline_2026-10-02_1843-records.ris
Avoid names such as:
final_search_NEW_v2.ris
Treat automated deduplication as a reviewable step
Duplicate detection is rarely a simple exact match. Titles change punctuation. Author lists are shortened. Conference abstracts later become journal articles. One trial may produce several legitimate reports.
In one evaluation, EndNote’s default author-year-title matching achieved 51% sensitivity and 99.83% specificity, meaning it missed nearly half of the duplicate citations in the test set (Rathbone et al., 2015). A later evaluation reported that Deduklick, a multistep automated deduplication system, reached 99.51% recall and 100.00% precision (Borissov et al., 2022). These results do not mean every team needs a custom algorithm. They show why the deduplication method and uncertain matches deserve inspection.
Keep separate counts for:
- Records imported
- Exact duplicates removed
- Probable duplicates reviewed
- Records merged
- Related reports retained because they describe the same study but contain different information
Do not confuse a duplicate record with a secondary report of the same study. One should usually be removed. The other may contain outcome, follow-up, protocol, or adverse-event information needed later.
Practical checkpoint: Can you explain why each removed record was considered a duplicate rather than a separate report?
Step 4: Pilot the eligibility criteria
Eligibility criteria that look clear in a protocol often become ambiguous when reviewers meet real abstracts.
Before screening the full set, ask every reviewer to classify the same small sample. Include:
- Obvious inclusions
- Obvious exclusions
- Borderline populations
- Unclear study designs
- Conference abstracts
- Protocols
- Secondary analyses
- Records with poor abstracts
Discuss disagreements. Then rewrite the criteria in operational terms.
Instead of:
Include studies of digital learning.
Use:
Include empirical studies evaluating a digital tool used by enrolled postsecondary students. Exclude administrative systems, faculty-only tools, opinion pieces, and studies without a measured learner outcome.
Record the clarification in the decision guide. If it changes the original eligibility criteria, add it to the protocol amendment log.
The goal is not perfect agreement for its own sake. The goal is to expose terms that different reviewers interpret differently before those differences spread across thousands of records.
Practical checkpoint: Would two reviewers apply each criterion the same way to a difficult abstract?
Step 5: Run independent screening and preserve the decisions
Screening usually happens in two stages:
- Title and abstract screening
- Full-text review
At both stages, follow the process defined in the protocol. If independent review is required, one reviewer should not see the other reviewer’s decision before recording their own.
For each record, preserve:
- Reviewer decisions
- Decision timestamps where available
- Conflicts
- Conflict-resolution outcomes
- Full-text retrieval status
- The final inclusion decision
- The primary reason for full-text exclusion
PRISMA 2020 asks teams to report how records were screened, how many reviewers participated, whether they worked independently, and how automation was used (Page et al., 2021).
Use one specific reason for each full-text exclusion
Avoid vague labels such as “not relevant.”
Use structured reasons tied to the protocol:
- Wrong population
- Wrong intervention or exposure
- Wrong comparator
- Wrong outcome
- Ineligible study design
- Outside the date range
- Not an empirical study
- Duplicate report with no additional eligible data
- Full text unavailable after the documented retrieval process
Assign the reason that most directly explains why the report failed eligibility. A consistent reason hierarchy makes the PRISMA total easier to reconcile.
Keep records and reports distinct
A review may include one study described across a protocol, conference abstract, primary article, follow-up article, and registry entry.
PRISMA distinguishes between:
- Studies: the underlying investigations
- Reports: the articles, abstracts, registrations, or other documents describing those studies (Page et al., 2021)
Preserve report-level screening decisions, then connect related reports to a shared study identifier before extraction and synthesis.
Where automation can help with screening
Machine learning can reorder a screening queue so likely relevant records appear earlier. This can help teams begin full-text retrieval and extraction while screening continues (Marshall & Wallace, 2019).
It does not automatically make unscreened records ineligible.
In an evaluation across 27 systematic reviews, heuristic stopping rules retrieved 95% of relevant abstracts while reducing the screening workload for irrelevant records by an average of 58% (Campos et al., 2024). Across six other datasets, active-learning models reduced the number of records needed to find 95% of the relevant studies by 63.9% to 91.7%, measured as Work Saved over Sampling at 95% recall (Ferdinands et al., 2023). Those gains depend on the dataset, model, seed decisions, and stopping rule. They are evidence for validated prioritization, not permission to hide unscreened records.
If your protocol uses active learning or another prioritization system, define and report:
- The tool and version
- How the initial training set was chosen
- Whether the system prioritized or excluded records
- How reviewer labels updated the model
- The validation process
- The target recall
- The stopping rule
- The number of records excluded or deprioritized through automation
- The human quality check
A defensible stopping rule is planned before the team becomes tired of screening.
For example, statistical stopping criteria can test whether a target recall level has likely been reached at a chosen confidence level. One evaluated approach produced an average 17% reduction in screening workload while applying a statistical guarantee (Callaghan & Müller-Hansen, 2020).
The SAFE procedure uses four phases: a random warm-up sample, active-learning screening, model switching, and a quality-evaluation check. Its stopping conditions include retrieving known key sources, screening against an estimated relevant-record count, covering a minimum portion of the dataset, and checking a final sequence of records that contains no relevant items (Boetje & van de Schoot, 2024).
These methods can reduce work. They do not remove author responsibility for the evidence that may have been missed.
Practical checkpoint: If screening stopped early, can you explain the stopping rule without saying, “The model seemed finished”?
Step 6: Test the extraction form on difficult studies
Build the extraction form from the synthesis plan, not from the first included study.
Potential fields include:
- Study identifier
- Report identifier
- Citation
- Country and setting
- Study design
- Recruitment dates
- Participant characteristics
- Intervention or exposure
- Comparator
- Outcome definition
- Measurement time point
- Group sizes
- Effect estimate
- Measure of uncertainty
- Missing-data handling
- Funding
- Conflicts of interest
- Notes for risk-of-bias assessment
- Exact source location
Start with several difficult studies. Test multi-arm designs, repeated time points, inconsistent terminology, missing statistics, and multiple reports from one study.
Revise ambiguous fields before the full extraction begins.
Link every extracted value to its source
A useful extraction entry should answer:
- Which report supplied this value?
- Where does it appear?
- Which table, figure, page, or section supports it?
- Was the value reported directly or calculated?
- Who extracted it?
- Who verified it?
- Was a correction made later?
Data extraction errors have reached rates of up to 50% in methodological evaluations, and single extraction produces more errors than independent double extraction (Mathes et al., 2017; Buscemi et al., 2006).
A generated field can be a useful first pass. It should not flow directly into a synthesis table without checking the source.
Practical checkpoint: Can a second reviewer open the exact passage behind every number used in the analysis?
Step 7: Assess risk of bias with the right tool
Risk of bias is not a generic quality score.
The tool should match the study design and the effect being assessed.
For randomized trials, RoB 2 uses signalling questions across five domains:
- Randomization process
- Deviations from intended interventions
- Missing outcome data
- Measurement of the outcome
- Selection of the reported result (Sterne et al., 2019)
For non-randomized intervention studies, ROBINS-I assesses seven domains:
- Confounding
- Selection of participants
- Classification of interventions
- Deviations from intended interventions
- Missing data
- Measurement of outcomes
- Selection of the reported result (Sterne et al., 2016)
Do not apply one “quality checklist” to every design simply because the form is familiar.
Calibrate the reviewers before full assessment
A named tool does not remove judgment.
One evaluation of RoB 2 found low agreement for overall judgments, with a Fleiss’ kappa of 0.16 and an average assessment time of 28 minutes per study outcome (Minozzi et al., 2020). That is a reason to pilot and discuss the domains, not a reason to abandon structured appraisal.
Before the full assessment:
- Rate the same studies independently
- Compare the supporting evidence, not only the final label
- Agree on how protocol deviations and missing outcomes will be handled
- Document decision rules
- Repeat the calibration if new study designs appear
Passage-highlighting tools can help reviewers find relevant methods text. They should not make the final risk-of-bias judgment.
Step 8: Hand clean data into the synthesis
Not every systematic review needs a meta-analysis.
Before combining studies, check whether they are sufficiently aligned in:
- Population
- Intervention or exposure
- Comparator
- Outcome definition
- Time point
- Study design
- Effect measure
- Clinical or conceptual context
If studies cannot be meaningfully pooled, use a structured narrative synthesis rather than forcing a summary estimate.
PRISMA 2020 separates synthesis reporting into several decisions, including study eligibility for each synthesis, data preparation, tabulation and visual display, synthesis methods, exploration of heterogeneity, and sensitivity analyses (Page et al., 2021).
If quantitative analysis is appropriate, decide how to handle:
- Multiple outcomes
- Multiple intervention arms
- Repeated measurements
- Clustered designs
- Missing summary statistics
- Different effect measures
- Statistical heterogeneity
- Sensitivity analyses
- Study dependence
The method should follow from the question, design, data, and intended claim. Our guide to data analysis methods covers that selection process in more detail.
Keep risk of bias and certainty separate
Risk of bias evaluates possible distortion within an individual study result.
Certainty assessment considers the body of evidence supporting an outcome. GRADE classifies certainty as high, moderate, low, or very low and considers domains including risk of bias, inconsistency, indirectness, imprecision, and publication bias (Guyatt et al., 2008).
A review can contain several well-conducted studies and still have low certainty because the evidence is inconsistent, indirect, or imprecise.
Practical checkpoint: Does the synthesis answer the protocol question, or did the available data quietly change the question?
Step 9: Reconcile the PRISMA flow diagram
Do not wait until manuscript submission to reconstruct the record counts.
Track the flow while the review is running.
At minimum, reconcile:Records identified−duplicates removed=records screenedRecords screened−records excluded=reports soughtReports sought−reports not retrieved=reports assessedReports assessed−full-text exclusions=included reports
Also confirm:
- Full-text exclusion reasons sum to the total excluded reports
- Included-report counts match the report inventory
- Included-study counts match the study inventory
- Database totals match the preserved raw exports
- Automation exclusions are reported separately where required
- Records found through citation searching or other methods use the correct pathway
PRISMA 2020 provides separate flow-diagram pathways for records identified through databases and registers and records found through other methods (Page et al., 2021).
The diagram should be an output of the screening record, not a manually reconstructed illustration.
For templates and worked examples, use our complete guide to PRISMA flow diagrams.
Practical checkpoint: Can every number in the diagram be reproduced from a saved export or system count?
Step 10: Complete the checklist and archive the review
Run the PRISMA checklist against the final manuscript.
Confirm that the report explains:
- The rationale and objective
- Eligibility criteria
- Information sources
- Complete search strategies
- Selection procedures
- Data collection
- Data items
- Risk-of-bias methods
- Effect measures
- Synthesis methods
- Reporting-bias assessment
- Certainty assessment
- Study-selection results
- Excluded reports
- Study characteristics
- Risk-of-bias results
- Synthesis results
- Limitations
- Registration and protocol access
- Amendments
- Support and conflicts
- Data, code, and material availability
Then archive:
- The registered protocol
- Protocol amendments
- Raw search exports
- Search strategies
- Deduplication records
- Screening decisions
- Exclusion reasons
- Study and report mappings
- Extraction forms
- Risk-of-bias decisions
- Analysis data
- Statistical code
- Tables and figures
- PRISMA checklist
- PRISMA flow diagram
- Software names and versions
An archive should help the team answer questions after publication and make an update possible without rebuilding the review from memory.
A systematic review workflow checklist
Before searching
- Write the review question.
- Define eligibility criteria.
- Assign reviewer roles.
- Select risk-of-bias tools.
- Define extraction fields.
- Plan the synthesis.
- Define any automation and validation procedures.
- Register the protocol.
- Start an amendment log.
Before screening
- Save the raw export from every source.
- Record each search date and result count.
- Peer-review the primary search strategy.
- Document the deduplication method.
- Inspect uncertain duplicate matches.
- Pilot the eligibility criteria.
- Clarify ambiguous rules.
Before extraction
- Connect multiple reports from the same study.
- Test the extraction form on difficult studies.
- Define source-location fields.
- Define the verification procedure.
- Pilot the risk-of-bias tool.
- Record calibration decisions.
Before synthesis
- Verify all extracted values.
- Confirm compatible outcomes and time points.
- Resolve unit and effect-measure differences.
- Apply the planned risk-of-bias process.
- Document deviations from the analysis plan.
- Run sensitivity checks where specified.
Before submission
- Reconcile every PRISMA count.
- Confirm exclusion reasons sum correctly.
- Separate included studies from included reports.
- Complete the PRISMA checklist.
- Report automation methods and exclusions.
- Verify the search is current enough for submission.
- Archive the protocol, data, decisions, and code.
Where software belongs in the workflow
No single platform is automatically the best choice for every stage.
A screening system may be excellent at independent decisions and conflict resolution but offer limited support for synthesis. Statistical software may produce the meta-analysis but know nothing about the search. A research workspace may help with discovery, evidence organization, and reporting without replacing protocol-required blinded screening.
Choose each tool by the decision it must preserve.
Our systematic review software comparison covers eight options by best fit, strengths, cost model, limitations, and pipeline stage.
Where CoChat fits
CoChat can help teams:
- Search across scholarly sources
- Keep source metadata attached
- Verify citations
- Build editable literature-review tables
- Organize source-linked synthesis notes
- Create PRISMA artifacts
- Keep files, decisions, and outputs together in a project
It does not replace protocol-required blinded dual screening, expert risk-of-bias judgment, or validated statistical software for meta-analysis.
Use it to reduce clerical work and keep the evidence easier to inspect. The researchers remain the authors and verifiers.
Map your systematic review workflow in CoChat.
Frequently asked questions
What are the main steps in a systematic review workflow?
A typical workflow includes protocol development, search design, retrieval, deduplication, screening, data extraction, risk-of-bias assessment, synthesis, certainty assessment, PRISMA reporting, and archiving.
The exact stages vary by review type. The important part is to define the decisions and preserve the handoffs between them.
Is PRISMA a methodology?
No. PRISMA is a reporting guideline. It helps authors report why a review was done, what they did, what they found, and what the results mean. It does not determine the review question, eligibility criteria, search quality, appraisal tool, or synthesis method.
Should I register a systematic review protocol?
Prospective registration makes the original methods visible and gives readers a way to compare the finished review with the planned review. Choose a registry that accepts your review type and field, then preserve dated amendments rather than overwriting the plan.
How many reviewers should screen sources?
Follow the protocol and the standards relevant to your field. Many systematic reviews use two independent reviewers for screening, with a documented process for resolving conflicts. Report how many reviewers participated and whether they worked independently.
Can AI screen sources for a systematic review?
AI can prioritize records, highlight likely evidence, and reduce repetitive work. If it is used to exclude records or stop screening early, the team needs a validated, prespecified procedure and transparent reporting. Researchers remain accountable for missed evidence and final eligibility decisions.
Can AI extract data for a systematic review?
AI can suggest fields or locate candidate passages. Every important value should still be checked against the original report before it enters the synthesis. Keep the source location beside the extracted value.
When should I create the PRISMA flow diagram?
Track the required counts from the first search onward. Generate the final diagram after screening and study-report reconciliation, then verify it against the preserved exports and decision logs.
Build the review so the final report is already supported
The best time to think about PRISMA is not the night before submission.
Start with the protocol. Preserve each search. Make screening decisions independently when required. Link every extracted value to the source. Use design-appropriate appraisal tools. Keep analysis choices visible. Reconcile the flow diagram from actual records.
The result is more than a polished systematic review. It is a review another researcher can inspect, understand, and update.
Start a CoChat research project and map each stage before choosing the tools.
References
Page, M. J., McKenzie, J. E., Bossuyt, P. M., Boutron, I., Hoffmann, T. C., Mulrow, C. D., Shamseer, L., Tetzlaff, J. M., Akl, E. A., Brennan, S. E., Chou, R., Glanville, J., Grimshaw, J. M., Hróbjartsson, A., Lalu, M. M., Li, T., Loder, E. W., Mayo-Wilson, E., McDonald, S., & Moher, D. (2021). The PRISMA 2020 statement: an updated guideline for reporting systematic reviews. BMJ. https://doi.org/10.1136/bmj.n71 [✓]
Shamseer, L., Moher, D., Clarke, M., Ghersi, D., Liberati, A., Petticrew, M., Shekelle, P., & Stewart, L. A. (2015). Preferred reporting items for systematic review and meta-analysis protocols (PRISMA-P) 2015 statement. Systematic Reviews. https://doi.org/10.1186/2046-4053-4-1 [✓]
Rethlefsen, M. L., Kirtley, S., Waffenschmidt, S., Ayala, A. P., Moher, D., Page, M. J., & Koffel, J. B. (2021). PRISMA-S: an extension to the PRISMA Statement for Reporting Literature Searches in Systematic Reviews. Systematic Reviews. https://doi.org/10.1186/s13643-020-01542-z [✓]
McGowan, J., Sampson, M., Salzwedel, D. M., Cogo, E., Foerster, V., & Lefebvre, C. (2016). PRESS Peer Review of Electronic Search Strategies: 2015 Guideline Statement. Journal of Clinical Epidemiology. https://doi.org/10.1016/j.jclinepi.2016.01.021 [✓]
Marshall, I. J., & Wallace, B. C. (2019). Toward systematic review automation: a practical guide to using machine learning tools in research synthesis. Systematic Reviews. https://doi.org/10.1186/s13643-019-1074-9 [✓]
Boetje, J., & van de Schoot, R. (2024). The SAFE procedure: a practical stopping heuristic for active learning-based screening in systematic reviews and meta-analyses. Systematic Reviews. https://doi.org/10.1186/s13643-024-02502-7 [✓]
Callaghan, M. W., & Müller-Hansen, F. (2020). Statistical stopping criteria for automated screening in systematic reviews. Systematic Reviews. https://doi.org/10.1186/s13643-020-01521-4 [✓]
Mathes, T., Klaßen, P., & Pieper, D. (2017). Frequency of data extraction errors and methods to increase data extraction quality: a methodological review. BMC Medical Research Methodology. https://doi.org/10.1186/s12874-017-0431-4 [✓]
Sterne, J. A. C., Savović, J., Page, M. J., Elbers, R. G., Blencowe, N. S., Boutron, I., Cates, C. J., Cheng, H. Y., Corbett, M. S., Eldridge, S. M., Emberson, J. R., Hernán, M. A., Hopewell, S., Hróbjartsson, A., Junqueira, D. R., Jüni, P., Kirkham, J. J., Lasserson, T., Li, T., & Higgins, J. P. T. (2019). RoB 2: a revised tool for assessing risk of bias in randomised trials. BMJ. https://doi.org/10.1136/bmj.l4898 [✓]
Sterne, J. A. C., Hernán, M. A., Reeves, B. C., Savović, J., Berkman, N. D., Viswanathan, M., Henry, D., Altman, D. G., Ansari, M. T., Boutron, I., Carpenter, J. R., Chan, A. W., Churchill, R., Deeks, J. J., Hróbjartsson, A., Kirkham, J., Jüni, P., Loke, Y. K., Pigott, T. D., & Higgins, J. P. T. (2016). ROBINS-I: a tool for assessing risk of bias in non-randomised studies of interventions. BMJ. https://doi.org/10.1136/bmj.i4919 [✓]
Guyatt, G. H., Oxman, A. D., Vist, G. E., Kunz, R., Falck-Ytter, Y., Alonso-Coello, P., & Schünemann, H. J. (2008). GRADE: an emerging consensus on rating quality of evidence and strength of recommendations. BMJ. https://doi.org/10.1136/bmj.39489.470347.ad [✓]
Minozzi, S., Cinquini, M., Gianola, S., González-Lorenzo, M., & Banzi, R. (2020). The revised Cochrane risk-of-bias tool for randomised trials (RoB 2) showed low inter-rater reliability and challenges in its application. Journal of Clinical Epidemiology. https://doi.org/10.1016/j.jclinepi.2020.06.015 [✓]
Rathbone, J., Carter, M., Hoffmann, T., & Glasziou, P. (2015). Better duplicate detection for systematic reviewers: evaluation of Systematic Review Assistant-Deduplication Module. Systematic Reviews. https://doi.org/10.1186/2046-4053-4-6 [✓]
Borissov, N., Haas, Q., Minder, B., Kopp-Heim, D., von Gernler, M., Janka, H., Teodoro, D., & Amini, P. (2022). Reducing systematic review burden using Deduklick: a novel, automated, reliable, and explainable deduplication algorithm to foster medical research. Systematic Reviews. https://doi.org/10.1186/s13643-022-02045-9 [✓]
Campos, D. G., Fütterer, T., Gfrörer, T., Lavelle-Hill, R., Murayama, K., König, L., Hecht, M., Zitzmann, S., & Scherer, R. (2024). Screening Smarter, Not Harder: A Comparative Analysis of Machine Learning Screening Algorithms and Heuristic Stopping Criteria for Systematic Reviews in Educational Research. Educational Psychology Review. https://doi.org/10.1007/s10648-024-09862-5 [✓]
Ferdinands, G., Schram, R., de Bruin, J., Bagheri, R. A., Oberski, D. L., Tummers, L., Teijema, J., & van de Schoot, R. (2023). Performance of active learning models for screening prioritization in systematic reviews: a simulation study into the Average Time to Discover relevant records. Systematic Reviews. https://doi.org/10.1186/s13643-023-02257-7 [✓]
Buscemi, N., Hartling, L., Vandermeer, B., Tjosvold, L., & Klassen, T. P. (2006). Single data extraction generated more errors than double data extraction in systematic reviews. Journal of Clinical Epidemiology. https://doi.org/10.1016/j.jclinepi.2005.11.010 [✓]